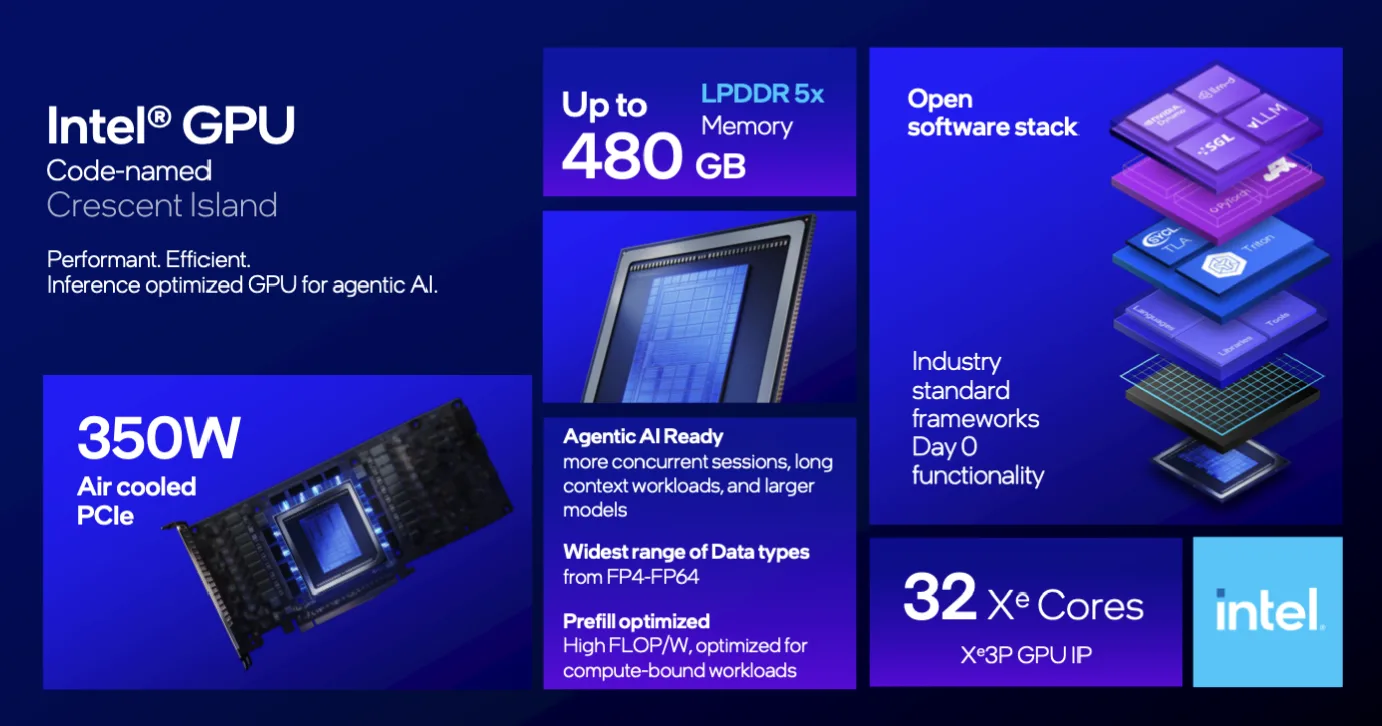
Intel introduced its new Intel GPU D-Series at this year’s 2026 Open Compute Global Summit. The Intel GPU D270 is the first inference accelerator based on its Crescent Island architecture, a 350W, air-cooled, double-wide PCIe Gen5 card built on Intel’s Xe3P architecture.
The part clocks in at 1.3 petaflops of dense FP8 matrix throughput and 1.5 TB/s of memory bandwidth, with 160GB of LPDDR5X on Intel’s own card and up to 480GB on partner designs. Intel is sampling the D270 with customers but has not yet announced pricing or a general availability date.
The D270 is Intel’s first commercial AI-focused data center GPU since Ponte Vecchio, following the cancellation of Rialto Bridge and Falcon Shores. It targets enterprise and service-provider inference that requires large memory pools within existing air-cooled racks.
Technical Details
Most of the architectural detail behind the card comes from Intel’s Hot Chips 2026 presentation, delivered by Chief Enterprise AI Systems Architect Sumit Mohan and Intel Fellow Hong Jiang.
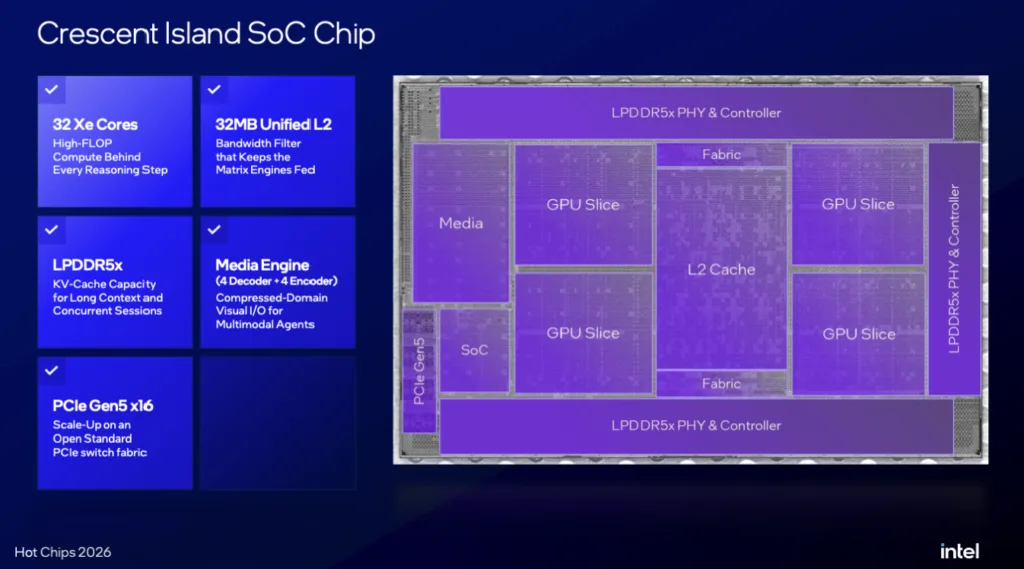
The D270 pairs a compute-dense GPU with an LPDDR5X memory subsystem sized for capacity. Intel removed graphics-specific hardware, including ray-tracing units, and reallocated that die area to matrix compute, resulting in the following feature set:
| Specification | Intel GPU D270 |
| Architecture | Xe3P (codename Crescent Island) |
| Compute units | 32 Xe cores in four slices, 256 XMX matrix engines, 256 vector engines |
| Clock speed | Approximately 2.5 GHz (derived from published FP8 rating) |
| Peak FP8 matrix | 1.3 PFLOPS dense |
| Peak FP64 vector | 10.2 TFLOPS |
| On-die memory | 1MB register file and 512KB L1/SLM per Xe core, 32MB unified L2 |
| Memory capacity | 160GB LPDDR5X (Intel card), up to 480GB (partner cards) |
| Memory bandwidth | 1.5 TB/s |
| Interface and form factor | PCIe Gen5 x16, double-wide CEM card, air-cooled |
| Power | 350W TDP |
| Media engine | Four encoders, four decoders |
| Availability | Customer sampling; pricing and GA date not announced |
Xe3P Compute Engine
Crescent Island is built from four Xe3P slices, each with eight Xe cores, and each core holds eight vector engines and eight XMX matrix engines (and is Intel’s third-generation Xe Matrix Extensions).
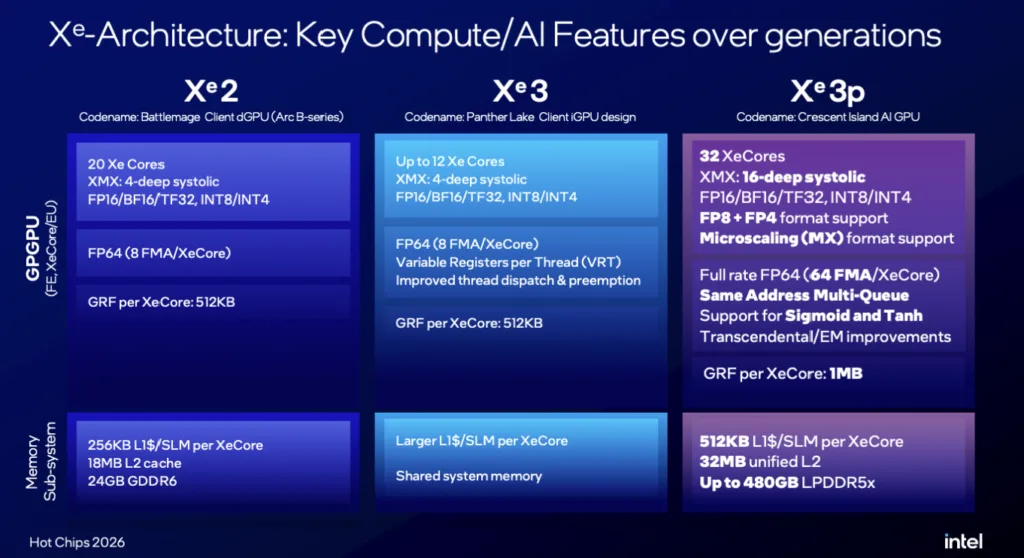
The most consequential change from prior generations is systolic depth. Xe3P XMX engines use a 16-deep systolic array, up from the four-deep design in Xe2 (Battlemage) and Xe3 (Panther Lake), allowing each engine to process larger matrix tiles per operation.
Intel also made several other changes to the core:
- The general register file doubles to 1MB per Xe core, up from 512KB on Xe2, reducing register spills when feeding the larger matrix engines.
- Each Xe core has 512KB of L1 cache or shared local memory, double the 256KB on Battlemage.
- Data type support spans FP4 with microscaling (MXFP4) through full-rate FP64, backed by 64 FP64 FMA units per Xe core. Intel presents this as making the part suitable for converged HPC and AI workloads.
- Hardware support for sigmoid and tanh transcendental functions accelerates the softmax and activation steps during inference.
Memory Subsystem
The Intel-built reference card uses twenty 8GB LPDDR5X devices for 160GB, and partner cards can use up to 24GB devices reach 480GB.
That puts the interface at an estimated 1,280 bits across 80 channels running near 9,375 MT/s, yielding the 1.5 TB/s Intel announced with the D270.
Prefill and Speculative Decoding
Intel designed the D270 around tokens per watt and specifically called out prefill (the compute-bound phase that processes prompts and builds the KV cache) as its primary design target.
Agentic workflows amplify prefill demand because agents repeatedly ingest long contexts, tool outputs, and retrieved documents. Intel also addresses decode, the memory-bandwidth-bound phase where LPDDR5X is weakest.
At Hot Chips, the company presented measurements on frontier MoE models, showing that, with an eight-token draft tree, speculative decoding retires 2.9 to 4.9 tokens per verification pass, arguing that it puts otherwise idle compute to work during generation.
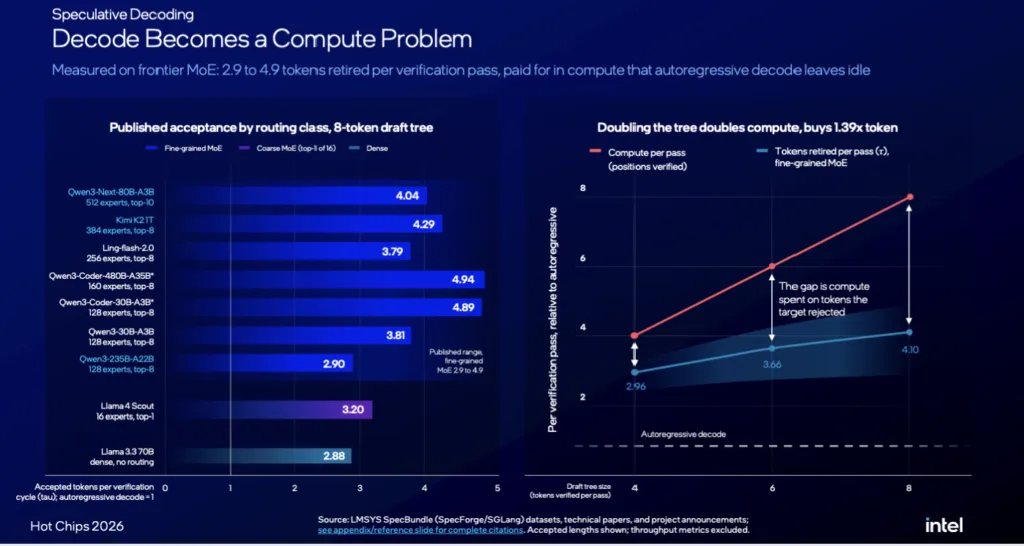
The published figures for the D270 reinforce this orientation. At 1.3 PFLOPS and 1.5 TB/s, the D270 delivers roughly 870 FP8 operations per byte of memory bandwidth.
That ratio favors compute-heavy phases and leaves the card reliant on speculative techniques and batching to keep decode efficient.
Software and Scale-Up
Intel can scale D270 deployments over standard PCIe Gen5 x16 links using an open switch fabric, with no proprietary interconnect.
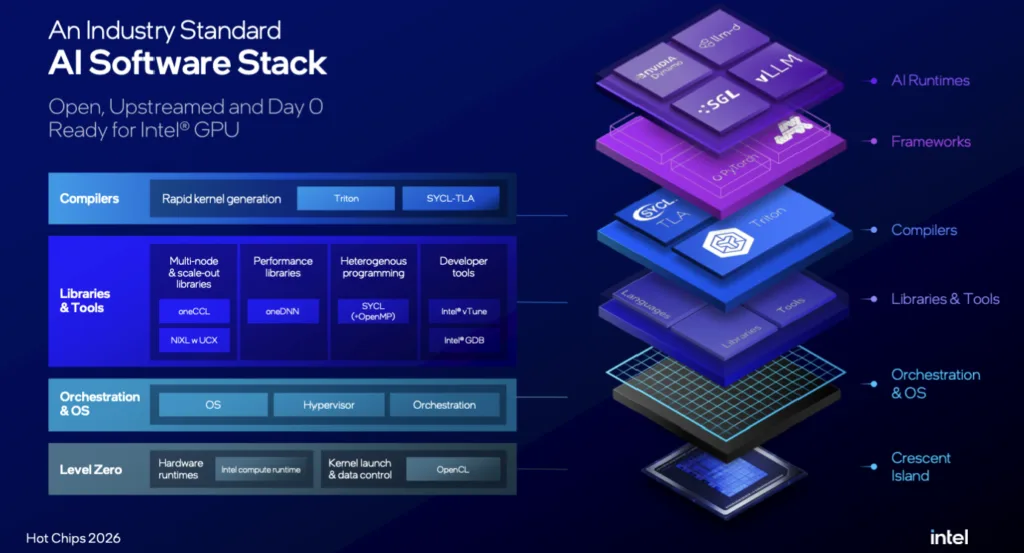
On the software side, Intel listed support for vLLM, SGLang, llm-d, and NVIDIA Dynamo, along with KV-cache-aware routing and offloading for orchestration across heterogeneous infrastructure.
The underlying stack includes Triton, SYCL-TLA, oneDNN, oneCCL, SYCL, and Level Zero with an OpenCL compute runtime.
Intel offers zero-day support for leading open models, and upstream Linux driver work for Crescent Island is already well underway.
Analysis
The D-Series gives Intel a coherent data center GPU story after years of roadmap churn. Ponte Vecchio saw limited commercial traction, Rialto Bridge was canceled in 2023, and Falcon Shores was withdrawn from the commercial product lineup in 2025.
Crescent Island narrows Intel’s ambition to a segment it can address with a single PCIe card, standard servers, and its existing Xeon installed base, while avoiding direct competition with NVIDIA and AMD’s rack-scale systems.
The strategy carries clear strengths alongside a few exposed points:
- Intel’s agentic AI framing is grounded in a real workload trend, as long-context agents shift demand toward prefill and memory capacity.
- The Xeon pairing gives Intel’s OEM partners, including Dell, HPE, and ASUS, a complete Intel inference server to sell to existing enterprise accounts.
- The SambaNova relationship supports a disaggregated model in which D270 cards handle prefill and other accelerators handle decode, thereby expanding the role of a bandwidth-limited component.
- Timing is the biggest risk. Intel originally targeted the second half of 2026, and with no launch date announced, volume availability now appears to be a 2027 event, by which point NVIDIA and AMD will have refreshed their PCIe offerings.
- The thesis that capacity and bandwidth have decoupled depends on continued MoE adoption and speculative gains from decoding. A shift back toward dense models would weaken the D270’s case.
Practitioner Impact
The D270 is targeted at enterprise AI platform teams, SaaS and GPU-as-a-service providers, and sovereign-cloud operators that want to serve large open models without rebuilding facilities.
The 350W air-cooled envelope and standard PCIe form factor let these buyers add inference capacity to existing servers and racks, avoiding the liquid-cooling and power upgrades that rack-scale HBM systems require.
Practitioners should weigh several factors before committing to the platform:
- Capacity per card changes model placement: A 480GB partner card holds the FP8 weights of models that would otherwise be split across multiple smaller-memory GPUs, simplifying the serving topology and reducing inter-card traffic.
- Decode-heavy workloads warrant testing: Chat-style applications with short prompts and long outputs rely on memory bandwidth, where the D270 trails HBM accelerators by a wide margin.
- Software maturity is the primary operational risk: Intel’s coverage in vLLM and SGLang lags CUDA in the breadth of optimized kernels, and teams should validate their specific models and serving recipes during sampling.
- Pricing remains unknown: LPDDR5X costs have been volatile, and the economics of the 480GB configuration depend heavily on DRAM pricing.
- PCIe-only scale-up limits large tensor-parallel deployments: The card is best suited for models that run on a single card or a small group of cards.
| Analyst Take The D270’s value case is strongest for prefill-heavy, long-context agentic workloads on models that fit in one or two cards. Teams running short-prompt, long-output chat services should expect HBM-based cards to retain a per-token advantage. |
Competitive Impact
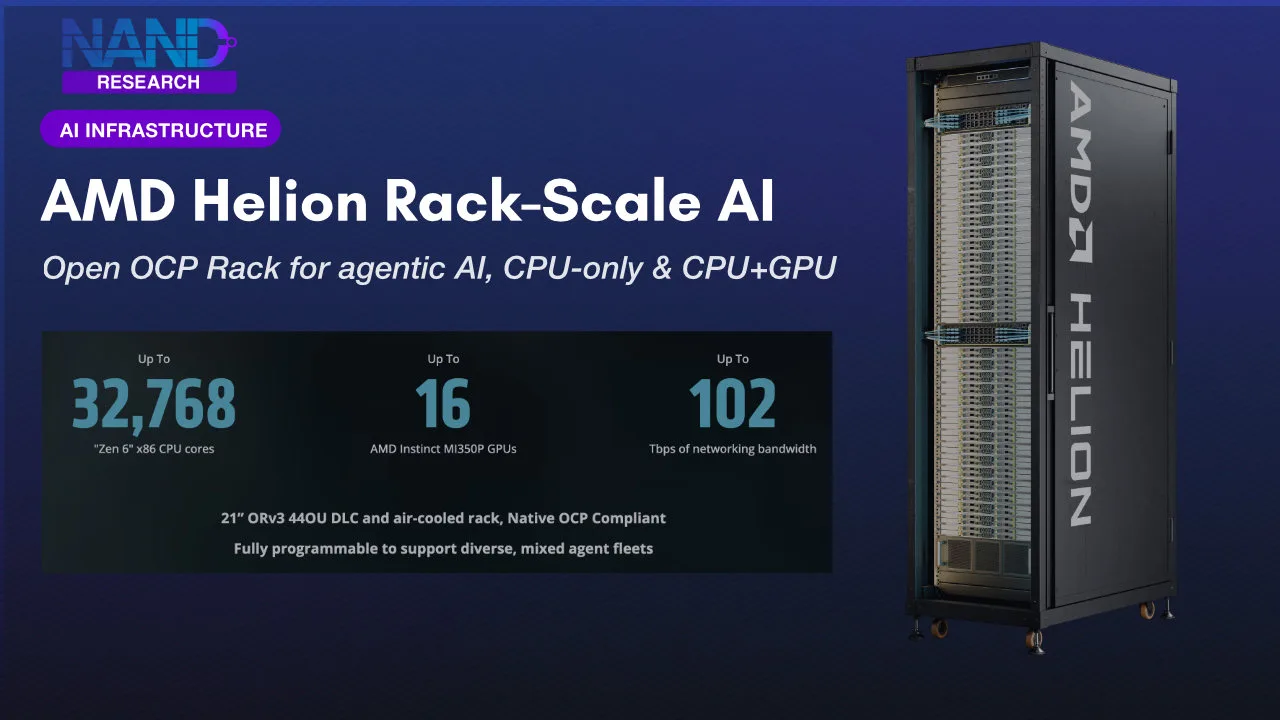
The D270 competes primarily against other PCIe inference accelerators that fit standard air-cooled servers. NVIDIA Vera Rubin and AMD MI455X rack-scale systems sit in a different tier, targeting maximum performance with liquid cooling and HBM4, though they compete for the same inference budgets at large service providers.
The table below summarizes the alternatives buyers are most likely to evaluate alongside the D270.
| Alternative | Model / Approach | Memory and Power | Compared to Intel GPU D270 |
| Intel GPU D270 | Inference-first Xe3P PCIe card | 160GB to 480GB LPDDR5X, 1.5 TB/s, 350W air-cooled | Reference point; leads on capacity per card and per watt, trails on bandwidth |
| AMD Instinct MI350P | CDNA 4 PCIe card with HBM | HBM3E, roughly 3.6 to 4 TB/s, up to 600W | About 2.3 PFLOPS dense FP8, roughly 75% more compute and more than twice the bandwidth; D270 counters with more capacity at lower power |
| NVIDIA RTX PRO 6000 Blackwell Server Edition | PCIe GPU on the CUDA stack | 96GB GDDR7, roughly 1.6 to 1.8 TB/s | Similar bandwidth with far less capacity; CUDA software depth remains NVIDIA’s decisive advantage |
| NVIDIA Vera Rubin and AMD MI455X | Rack-scale HBM4 systems | Liquid-cooled, HBM4 | Far higher per-accelerator performance for training and decode; requires facility upgrades the D270 avoids |
| SambaNova SN50 | Dataflow inference systems | Air-cooled racks | Intel partner; complementary in disaggregated serving with D270 handling prefill |
| Intel Gaudi 3 | Intel’s prior AI accelerator line | 128GB HBM2e | Existing Intel option; the D-Series moves Intel’s inference roadmap onto the Xe GPU software stack |
The D270’s differentiation is strongest on memory capacity per card and per watt. No other announced PCIe accelerator offers 480GB, and none approaches that capacity at 350W.
Its weakest points are memory bandwidth and software ecosystem depth. AMD’s MI350P delivers more compute and far more HBM bandwidth in the same form factor, and NVIDIA’s CUDA ecosystem remains the default for most inference teams.
Final Thoughts
Intel has delivered a well-reasoned architecture for a defined problem. The Hot Chips presentation on its internals shows deliberate engineering choices, including deeper matrix engines, doubled register and L1 capacity, broad data-type support, and a RAS feature set suited to production data centers.
The D-series announcement at OCP landed as we expected, which gives the D270 credibility without a surprise upside.
There are still significant open questions. Intel has not published pricing, a launch date, or independent performance data, and its data center GPU history gives buyers reason to wait for shipping hardware. LPDDR5X bandwidth also caps decode performance, which speculative decoding only partly offsets.
For enterprises that want to run large open models and long-context agents within the racks and power budgets they already have, the D270 is the most capacity-dense PCIe accelerator announced to date by any vendor.
The D-Series is Intel’s most credible entry into data center AI acceleration in five years, but converting that credibility into deployments now depends on shipping on schedule, maturing its software, and pricing the 480GB configuration competitively.